Interesting Finds — 2026-09-16
Five notes: Tailcat's accountless tunnels, Claude Money's trust question, System One models that cannot hallucinate, recursive self-improvement through dreaming, and an inbox for long-running agents.
archive register — 35 filed
The complete published record, newest first.
Five notes: Tailcat's accountless tunnels, Claude Money's trust question, System One models that cannot hallucinate, recursive self-improvement through dreaming, and an inbox for long-running agents.
Five notes: RTX Spark AI PCs, the Dime headset mystery, building too much, Runway's realtime worlds, and an anti-hallucination startup.
Five notes: Nvidia's Hydra-0 action-flow world model, a random human life, Google's Putty vibe-coding experiment, Qwen-RobotWorld, and a visual atlas of agent systems.
Two more: Tencent's WeKnora knowledge platform and a paper showing sliding-window attention beats linear retrofits.
Six notes: Cognition at 47 billion, a Tailwind resource index, goal loops that deliver, AI and the direction problem, crisis as building permission, and the second-brain implementation gap.
Five notes: the Astra recurrent-depth safety fight, agentic video in Gemini, the abliteration business question, DLSS 5 perception splits, and the Fed watching token prices.
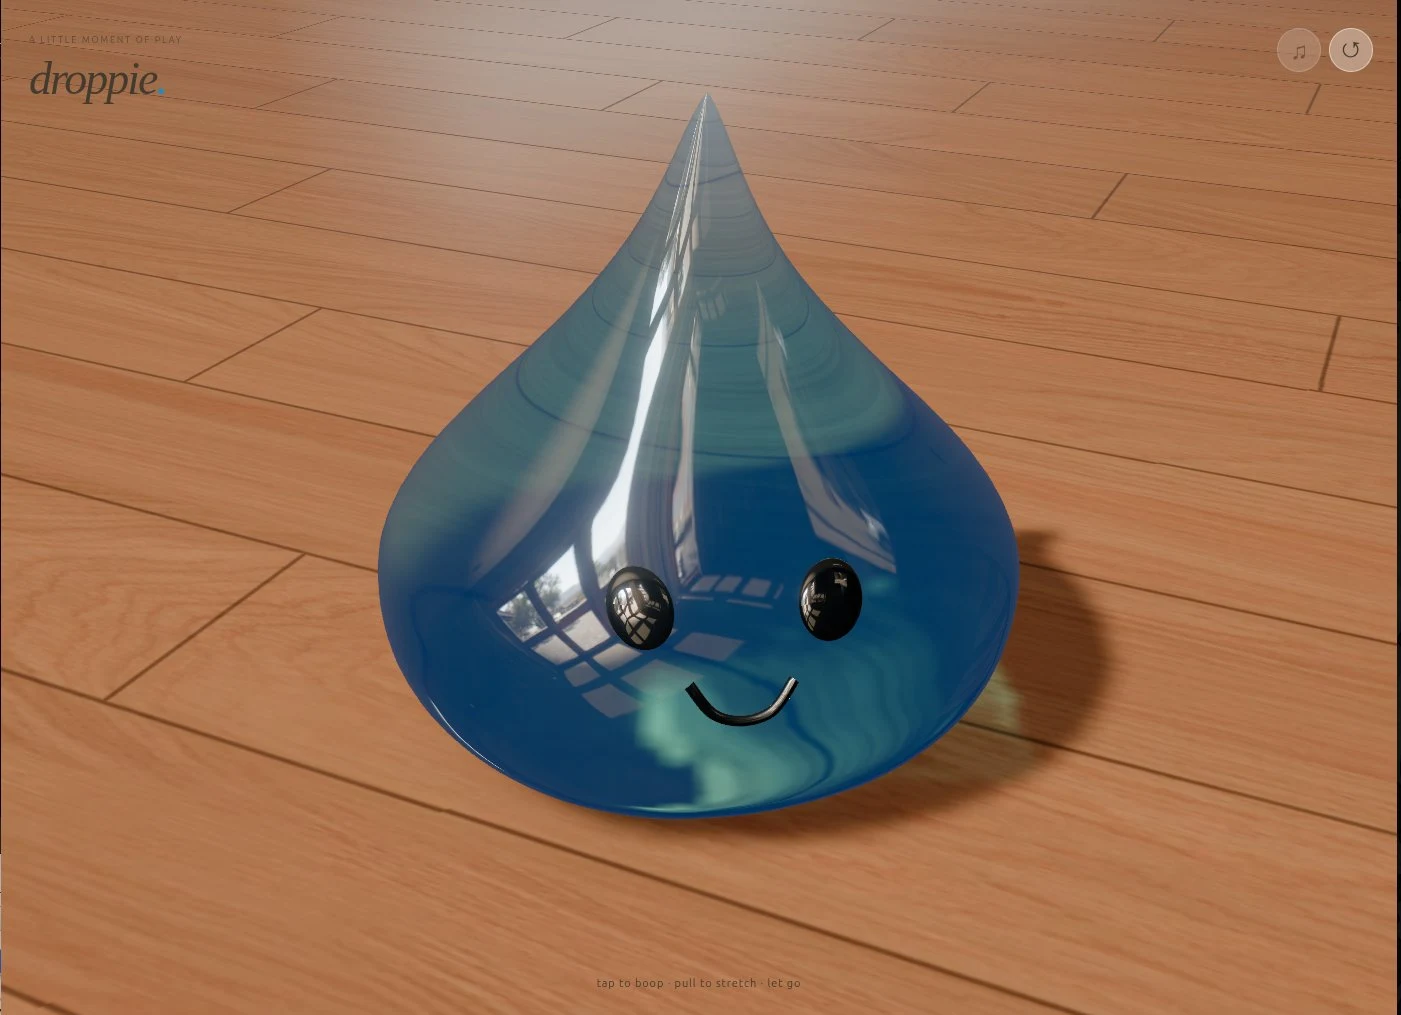
A tiny living water droplet built with GPT-6 Astra — soft-body physics, WebGPU refraction, and procedural audio.
Five notes: a one-shot web-demo bench, Cloudflare cache transcoding, Copilot cost efficiency, new knobs for the brain, and Fable 5.1 worlds from code.
Four notes: Raschka on looped transformers, TxBench antibody evals, Google Pics gated to paid tiers, and the Gemini Flash Cyber overlap.
Five more notes: Shumer's 3D-world loop, a benchmark that scores agent construction, Qwen-Drive-1.0, loop engineering patterns, and AlphaGenome Atlas.
Eleven more: Images 2.5, Mercury 2.5 diffusion, ID-V2V restyling, cross-model KV transfer, Muse, Gaussian Splat Lite, the KV-caching explainer, tgrep, DIY weather forecasting, a 1-meter LiDAR viewer, and Switzerland's open-source trial.
A manager loop running Muse Spark built a complete small game in a single 24-minute run. The structure did the work, not the spend.
Five notes: an SSH fighting game with a bot league, Muse Spark 1.3, the Muse superapp leak, test-time training as a scaling axis, and Meta's organizational second brain.
Three preprints on harness as infrastructure: HarnessDev measures whether LLMs can build their own scaffolding, Harness-of-Harness makes multi-day autonomy composable, and Fast Weight Attention fixes the temporal alignment of recurrent memory.
OpenAI's largest training run ships with critical-rated cyber capability, looped computation that weakens chain-of-thought monitoring, and task-based pricing pressure.
Seven notes: California youth-safety regulation, industrial overcapacity as science catalyst, robotics hardware takeoff, in-context learning's GPT moment, AI as wet-lab co-pilot, a productivity-miracle claim, and Gemini 3.8 Flash / Flash Cyber.
The same Golden Gate Park Three.js prompt across several models, with the artifact, one-shot result, wall time, and run harness kept together.
Seven notes: Qwen Max 0902's 2.4T post-train, Quasar 438B tops Europe, H3-World turns H3 into a world model with 0.2% params, Fable 5.1 decodes a 373-year cipher, Humain M3 in Arabic, a cancer-vaccine primer, plus Dyson's $499 camera-toothbrush — noted with editorial.
A one-line normalization of LoRA's A matrix restores balanced early gradients, faster convergence, and mergeability without extra parameters.
25% cheaper cache reads, 60% fewer cyber false positives, and early lab-validated science from a model that ships as two permissions, not two capabilities.
Five notes: JIT-Agent synthesizes harnesses on the fly, Michigan Robotics open-sources its curriculum, DualView publishes exact phase-specialized weights, plus an ESP32 dashboard and the long-lived free-APIs directory.
First natively multimodal in the GLM-5 line. 45 layers, hybrid linear-sparse attention with IndexPool, and Manifold-Constrained Hyper-Connections — MIT weights that stay local-feasible.
Multimodal MoE with GDN+QSA attention, gated residual, n-gram embedding, and Muon — an open-weight preview of the Qwen4 line.
Four notes from the feed: an experimental vision model, a free agentic model window, CUDA on RISC-V, and a Linux utility for Logitech hardware.
Five more notes: hardware-aware kernels, a tighter matrix multiplication bound, AMD credits, and two SemiAnalysis signals on the CUDA moat.
Diffusion for language, skill-aware RL, explorative modeling, looped MoEs, and a map of 733k papers.
Sleep for hybrids, aggressive diffusion decoding, AI-found test-time controllers, a virtual cell, a DeepSeek J-Space report, and PagedAttention explained.
Meta's Hatch and Watermelon, Perplexity's local-first Portable Computer, Figure's Index dataset, Amazon's automated last mile, Jetson Orin Nano 2, and Keenable's knowledge index.

Google DeepMind finetunes Gemma 4 into a discrete diffusion model that generates around 20 tokens per forward pass.
One setting keeps speculative decoding fast from 1 to 256 concurrent users by skipping low-confidence drafts when the GPU is busy.
27 billion dense, native vision-language, 262K to 1M context. Hybrid linear attention in a deployable package.
Meta distilled Spark for the workshop — a 30B model that runs locally and keeps the job on the bench.
13.5 million GitHub Copilot sessions show what happens after you press enter.
Hall proposes AI that makes democracy cheaper to run. The question is who keeps it running.
Google DeepMind open sourced its most accurate weather model. The mechanism is simpler than it looks.